Map the official objectives.
Read the current Databricks objectives and make a short list of the areas you need to revisit before booking DB-MLA.
Revizo / Databricks / DB-MLA
DATABRICKS CERTIFICATION STUDY GUIDE
Validates foundational skills in machine learning using Databricks platform.
Download Revizo
Validates foundational skills in machine learning using Databricks platform.
Exam details are based on the available Databricks catalogue information. Confirm current requirements with the exam provider before booking.
Use the provider's current objectives as your source of truth, then organise your Revizo sessions around data and AI workflows, platform capabilities and the practical decisions named in the certification. The DB-MLA exam is listed as Multiple choice and hands-on tasks; your starting point should reflect 6+ months of Databricks ML experience.
Read the current Databricks objectives and make a short list of the areas you need to revisit before booking DB-MLA.
Select DB-MLA in Revizo and use focused question sessions to test one topic or decision type at a time, rather than relying on a single long cram session.
Use your results to return to incorrect answers, revisit the official material behind them and repeat short DB-MLA practice sessions until the gaps are clearer.
FREE PRACTICE PREVIEW
Review each question, its correct answer and any available source explanation before continuing your certification study in Revizo.
Answers & available explanations
QUESTION 1
A machine learning engineer has created a Feature Table new_table using Feature Store Client fs. When creating the table, they specified a metadata description with key information about the Feature Table. They now want to retrieve that metadata programmatically.
Which of the following lines of code will return the metadata description?
Correct answer: C
QUESTION 2
A data scientist has a Spark DataFrame spark_df. They want to create a new Spark DataFrame that contains only the rows from spark_df where the value in column price is greater than 0.
Which of the following code blocks will accomplish this task?
Correct answer: B
QUESTION 3
A health organization is developing a classification model to determine whether or not a patient currently has a specific type of infection. The organization's leaders want to maximize the number of positive cases identified by the model.
Which of the following classification metrics should be used to evaluate the model?
Correct answer: E
QUESTION 4
In which of the following situations is it preferable to impute missing feature values with their median value over the mean value?
Correct answer: C
QUESTION 5
A data scientist has replaced missing values in their feature set with each respective feature variable’s median value. A colleague suggests that the data scientist is throwing away valuable information by doing this.
Which of the following approaches can they take to include as much information as possible in the feature set?
Correct answer: D
QUESTION 6
A data scientist is wanting to explore summary statistics for Spark DataFrame spark_df. The data scientist wants to see the count, mean, standard deviation, minimum, maximum, and interquartile range (IQR) for each numerical feature.
Which of the following lines of code can the data scientist run to accomplish the task?
Correct answer: A
QUESTION 7
An organization is developing a feature repository and is electing to one-hot encode all categorical feature variables. A data scientist suggests that the categorical feature variables should not be one-hot encoded within the feature repository.
Which of the following explanations justifies this suggestion?
Correct answer: E
QUESTION 8
A data scientist has created two linear regression models. The first model uses price as a label variable and the second model uses log(price) as a label variable. When evaluating the RMSE of each model by comparing the label predictions to the actual price values, the data scientist notices that the RMSE for the second model is much larger than the RMSE of the first model.
Which of the following possible explanations for this difference is invalid?
Correct answer: B
QUESTION 9
A data scientist uses 3-fold cross-validation when optimizing model hyperparameters for a regression problem. The following root-mean-squared-error values are calculated on each of the validation folds:
• 10.0
• 12.0
• 17.0
Which of the following values represents the overall cross-validation root-mean-squared error?
Correct answer: A
QUESTION 10
A machine learning engineer is trying to scale a machine learning pipeline pipeline that contains multiple feature engineering stages and a modeling stage. As part of the cross-validation process, they are using the following code block: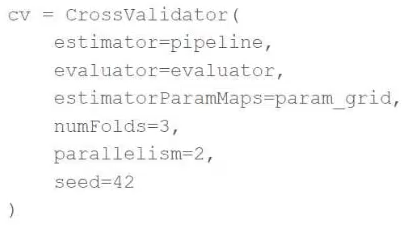
A colleague suggests that the code block can be changed to speed up the tuning process by passing the model object to the estimator parameter and then placing the updated cv object as the final stage of the pipeline in place of the original model.
Which of the following is a negative consequence of the approach suggested by the colleague?
Correct answer: B
QUESTION 11
What is the name of the method that transforms categorical features into a series of binary indicator feature variables?
Correct answer: C
QUESTION 12
A data scientist wants to parallelize the training of trees in a gradient boosted tree to speed up the training process. A colleague suggests that parallelizing a boosted tree algorithm can be difficult.
Which of the following describes why?
Correct answer: D
QUESTION 13
A data scientist wants to efficiently tune the hyperparameters of a scikit-learn model. They elect to use the Hyperopt library's fmin operation to facilitate this process. Unfortunately, the final model is not very accurate. The data scientist suspects that there is an issue with the objective_function being passed as an argument to fmin.
They use the following code block to create the objective_function: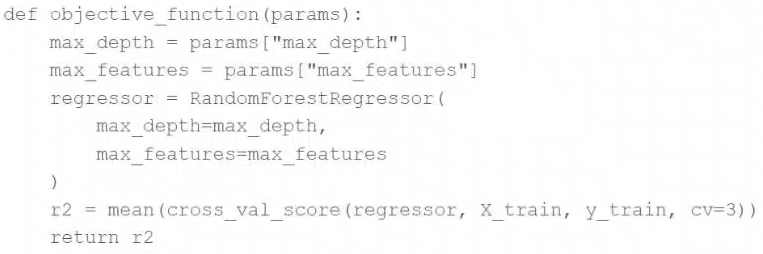
Which of the following changes does the data scientist need to make to their objective_function in order to produce a more accurate model?
Correct answer: D
QUESTION 14
A data scientist is attempting to tune a logistic regression model logistic using scikit-learn. They want to specify a search space for two hyperparameters and let the tuning process randomly select values for each evaluation.
They attempt to run the following code block, but it does not accomplish the desired task: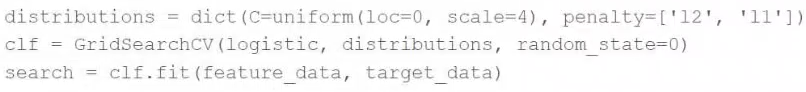
Which of the following changes can the data scientist make to accomplish the task?
Correct answer: A
QUESTION 15
Which of the following tools can be used to parallelize the hyperparameter tuning process for single-node machine learning models using a Spark cluster?
Correct answer: D
QUESTION 16
Which of the following describes the relationship between native Spark DataFrames and pandas API on Spark DataFrames?
Correct answer: C
QUESTION 17
A data scientist has written a data cleaning notebook that utilizes the pandas library, but their colleague has suggested that they refactor their notebook to scale with big data.
Which of the following approaches can the data scientist take to spend the least amount of time refactoring their notebook to scale with big data?
Correct answer: E
QUESTION 18
A data scientist has defined a Pandas UDF function predict to parallelize the inference process for a single-node model: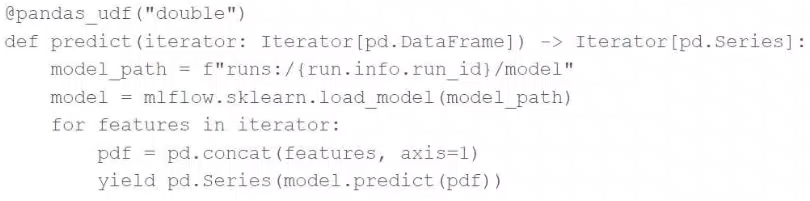
They have written the following incomplete code block to use predict to score each record of Spark DataFrame spark_df: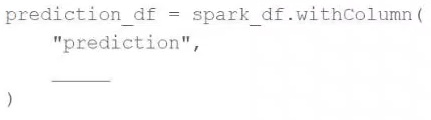
Which of the following lines of code can be used to complete the code block to successfully complete the task?
Correct answer: A
QUESTION 19
Which of the Spark operations can be used to randomly split a Spark DataFrame into a training DataFrame and a test DataFrame for downstream use?
Correct answer: E
QUESTION 20
A data scientist is using Spark ML to engineer features for an exploratory machine learning project.
They decide they want to standardize their features using the following code block: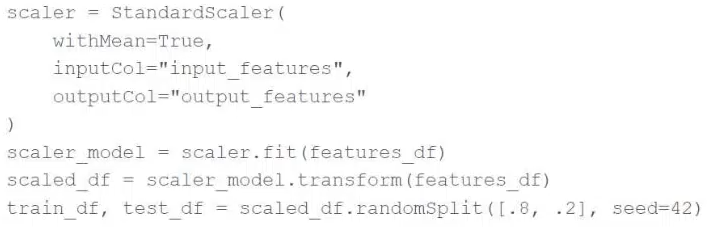
Upon code review, a colleague expressed concern with the features being standardized prior to splitting the data into a training set and a test set.
Which of the following changes can the data scientist make to address the concern?
Correct answer: E
Choose DB-MLA in Revizo and work through original, question-by-question practice on your iPhone. Review results, revisit what needs attention and keep your next session tied to one specific certification objective.
Practise DB-MLA with RevizoNo. Revizo is an independent iPhone app for certification practice. Refer to the provider's official resources for current exam policies and registration.
Use the exam code to select the matching certification in Revizo, then build short, focused sessions around the areas you want to review.
No. Revizo provides original practice questions for certification study. Use the provider's official objectives, documentation and policies as the source of truth for your preparation.
Use the current Databricks objectives, documentation and registration guidance as your source of truth. Revizo is designed to support focused practice, not replace the provider's official materials.
Check the official Databricks exam page for the latest objectives, registration details and policies.