Map the official objectives.
Read the current Databricks objectives and make a short list of the areas you need to revisit before booking DB-GAIEA.
Revizo / Databricks / DB-GAIEA
DATABRICKS CERTIFICATION STUDY GUIDE
Demonstrates foundational skills in generative AI engineering using Databricks.
Download Revizo
Demonstrates foundational skills in generative AI engineering using Databricks.
Exam details are based on the available Databricks catalogue information. Confirm current requirements with the exam provider before booking.
Use the provider's current objectives as your source of truth, then organise your Revizo sessions around data and AI workflows, platform capabilities and the practical decisions named in the certification. The DB-GAIEA exam is listed as Multiple choice and hands-on tasks; your starting point should reflect 6+ months of Databricks AI experience.
Read the current Databricks objectives and make a short list of the areas you need to revisit before booking DB-GAIEA.
Select DB-GAIEA in Revizo and use focused question sessions to test one topic or decision type at a time, rather than relying on a single long cram session.
Use your results to return to incorrect answers, revisit the official material behind them and repeat short DB-GAIEA practice sessions until the gaps are clearer.
FREE PRACTICE PREVIEW
Review each question, its correct answer and any available source explanation before continuing your certification study in Revizo.
Answers & available explanations
QUESTION 1
A Generative Al Engineer has created a RAG application to look up answers to questions about a series of fantasy novels that are being asked on the author’s web forum. The fantasy novel texts are chunked and embedded into a vector store with metadata (page number, chapter number, book title), retrieved with the user’s query, and provided to an LLM for response generation. The Generative AI Engineer used their intuition to pick the chunking strategy and associated configurations but now wants to more methodically choose the best values.
Which TWO strategies should the Generative AI Engineer take to optimize their chunking strategy and parameters? (Choose two.)
Correct answer: C, E
QUESTION 2
A Generative AI Engineer is designing a RAG application for answering user questions on technical regulations as they learn a new sport.
What are the steps needed to build this RAG application and deploy it?
Correct answer: B
QUESTION 3
A Generative AI Engineer just deployed an LLM application at a digital marketing company that assists with answering customer service inquiries.
Which metric should they monitor for their customer service LLM application in production?
Correct answer: A
QUESTION 4
A Generative AI Engineer is building a Generative AI system that suggests the best matched employee team member to newly scoped projects. The team member is selected from a very large team. The match should be based upon project date availability and how well their employee profile matches the project scope. Both the employee profile and project scope are unstructured text.
How should the Generative Al Engineer architect their system?
Correct answer: D
QUESTION 5
A Generative AI Engineer is designing an LLM-powered live sports commentary platform. The platform provides real-time updates and LLM-generated analyses for any users who would like to have live summaries, rather than reading a series of potentially outdated news articles.
Which tool below will give the platform access to real-time data for generating game analyses based on the latest game scores?
Correct answer: C
QUESTION 6
A Generative AI Engineer has a provisioned throughput model serving endpoint as part of a RAG application and would like to monitor the serving endpoint’s incoming requests and outgoing responses. The current approach is to include a micro-service in between the endpoint and the user interface to write logs to a remote server.
Which Databricks feature should they use instead which will perform the same task?
Correct answer: D
QUESTION 7
A Generative Al Engineer is tasked with improving the RAG quality by addressing its inflammatory outputs.
Which action would be most effective in mitigating the problem of offensive text outputs?
Correct answer: D
QUESTION 8
A Generative Al Engineer is creating an LLM-based application. The documents for its retriever have been chunked to a maximum of 512 tokens each. The Generative Al Engineer knows that cost and latency are more important than quality for this application. They have several context length levels to choose from.
Which will fulfill their need?
Correct answer: D
QUESTION 9
A small and cost-conscious startup in the cancer research field wants to build a RAG application using Foundation Model APIs.
Which strategy would allow the startup to build a good-quality RAG application while being cost-conscious and able to cater to customer needs?
Correct answer: B
QUESTION 10
A Generative Al Engineer is responsible for developing a chatbot to enable their company’s internal HelpDesk Call Center team to more quickly find related tickets and provide resolution. While creating the GenAI application work breakdown tasks for this project, they realize they need to start planning which data sources (either Unity Catalog volume or Delta table) they could choose for this application. They have collected several candidate data sources for consideration: call_rep_history: a Delta table with primary keys representative_id, call_id. This table is maintained to calculate representatives’ call resolution from fields call_duration and call start_time. transcript Volume: a Unity Catalog Volume of all recordings as a *.wav files, but also a text transcript as *.txt files. call_cust_history: a Delta table with primary keys customer_id, cal1_id. This table is maintained to calculate how much internal customers use the HelpDesk to make sure that the charge back model is consistent with actual service use. call_detail: a Delta table that includes a snapshot of all call details updated hourly. It includes root_cause and resolution fields, but those fields may be empty for calls that are still active. maintenance_schedule – a Delta table that includes a listing of both HelpDesk application outages as well as planned upcoming maintenance downtimes.
They need sources that could add context to best identify ticket root cause and resolution.
Which TWO sources do that? (Choose two.)
Correct answer: D, E
QUESTION 11
What is the most suitable library for building a multi-step LLM-based workflow?
Correct answer: D
QUESTION 12
When developing an LLM application, it’s crucial to ensure that the data used for training the model complies with licensing requirements to avoid legal risks.
Which action is NOT appropriate to avoid legal risks?
Correct answer: D
QUESTION 13
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.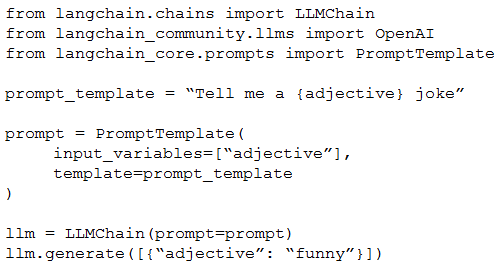
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
Correct answer: D
QUESTION 14
A Generative Al Engineer is creating an LLM system that will retrieve news articles from the year 1918 and related to a user's query and summarize them. The engineer has noticed that the summaries are generated well but often also include an explanation of how the summary was generated, which is undesirable.
Which change could the Generative Al Engineer perform to mitigate this issue?
Correct answer: D
QUESTION 15
A Generative Al Engineer has developed an LLM application to answer questions about internal company policies. The Generative AI Engineer must ensure that the application doesn’t hallucinate or leak confidential data.
Which approach should NOT be used to mitigate hallucination or confidential data leakage?
Correct answer: B
QUESTION 16
A Generative Al Engineer interfaces with an LLM with prompt/response behavior that has been trained on customer calls inquiring about product availability. The LLM is designed to output “In Stock” if the product is available or only the term “Out of Stock” if not.
Which prompt will work to allow the engineer to respond to call classification labels correctly?
Correct answer: D
QUESTION 17
A Generative Al Engineer is tasked with developing a RAG application that will help a small internal group of experts at their company answer specific questions, augmented by an internal knowledge base. They want the best possible quality in the answers, and neither latency nor throughput is a huge concern given that the user group is small and they’re willing to wait for the best answer. The topics are sensitive in nature and the data is highly confidential and so, due to regulatory requirements, none of the information is allowed to be transmitted to third parties.
Which model meets all the Generative Al Engineer’s needs in this situation?
Correct answer: D
QUESTION 18
A Generative Al Engineer would like an LLM to generate formatted JSON from emails. This will require parsing and extracting the following information: order ID, date, and sender email. Here’s a sample email: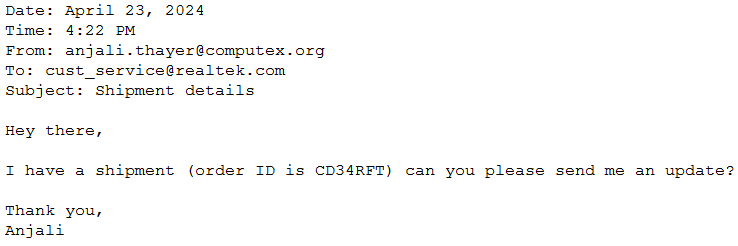
They will need to write a prompt that will extract the relevant information in JSON format with the highest level of output accuracy.
Which prompt will do that?
Correct answer: B
QUESTION 19
A Generative AI Engineer has been asked to build an LLM-based question-answering application. The application should take into account new documents that are frequently published. The engineer wants to build this application with the least cost and least development effort and have it operate at the lowest cost possible.
Which combination of chaining components and configuration meets these requirements?
Correct answer: A
QUESTION 20
A Generative AI Engineer is creating an agent-based LLM system for their favorite monster truck team. The system can answer text based questions about the monster truck team, lookup event dates via an API call, or query tables on the team’s latest standings.
How could the Generative AI Engineer best design these capabilities into their system?
Correct answer: B
Choose DB-GAIEA in Revizo and work through original, question-by-question practice on your iPhone. Review results, revisit what needs attention and keep your next session tied to one specific certification objective.
Practise DB-GAIEA with RevizoNo. Revizo is an independent iPhone app for certification practice. Refer to the provider's official resources for current exam policies and registration.
Use the exam code to select the matching certification in Revizo, then build short, focused sessions around the areas you want to review.
No. Revizo provides original practice questions for certification study. Use the provider's official objectives, documentation and policies as the source of truth for your preparation.
Use the current Databricks objectives, documentation and registration guidance as your source of truth. Revizo is designed to support focused practice, not replace the provider's official materials.
Check the official Databricks exam page for the latest objectives, registration details and policies.